Microsoft
Florence-2
About
Florence-2 is a 232M open-weight model from Microsoft. Vision foundation model for captioning, OCR, detection, and region tasks. It accepts text and images. Released June 15, 2024.
Parameters
232M
Published parameter count.
License
MIT
License on the weights.
Pricing
Token rates are US dollars per 1M tokens. Image rates are per 1K images. Audio rates are per 1M audio seconds.
| Rate | Price |
|---|---|
| Input / 1M | $0 |
| Output / 1M | $0 |
Compare
Florence-2 has the lowest published input rate of these OCR models, $0 / 1M input.
| Model | What it does | Price | Parameters | Context |
|---|---|---|---|---|
| Florence-2 | Vision foundation model for captioning, OCR, detection, and region tasks. | $0 / 1M input | 232M | — |
| PP-OCRv6 | PaddleOCR PP-OCRv6 medium text detection and recognition; scene OCR JSONL on image chat; text returns plain text; document_url fan-out via text. | $0.02 / 1M input | 20M | — |
| DeepSeek-OCR-2 | DeepSeek OCR 2 and markdown extraction. | $0.25 / 1M input | 3.4B | 8K |
| dots.mocr | Multilingual document layout parsing and markdown OCR. | $0.20 / 1M input | 3B | 24K |
Benchmarks
Published scores for Florence-2, from the Florence-2 model card.
- TextVQA63.6
| Reading | Example |
|---|---|
| Qualitative | Clear structure, grounded in the input |
| Quantitative | COCO caption CIDEr: 140. |
| Cost and performance | Lower listed rate, mid-pack latency |
Performance
Latency is the end-to-end round trip. Throughput is completion tokens divided by that time. It is a request rate, not decode speed.
Latency
317 ms
Throughput
—
Requests
354
Examples
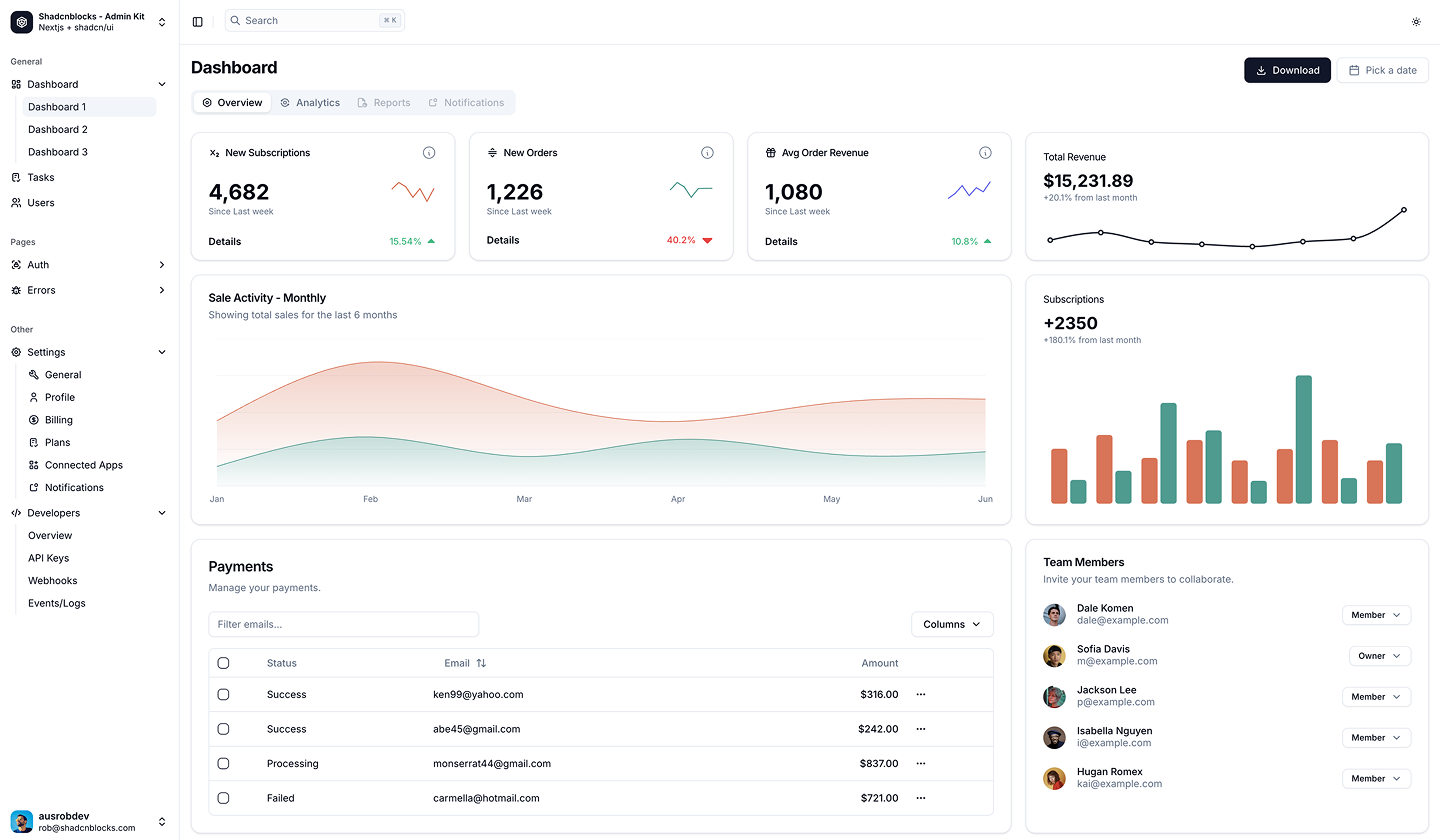
Caption a screenshot
caption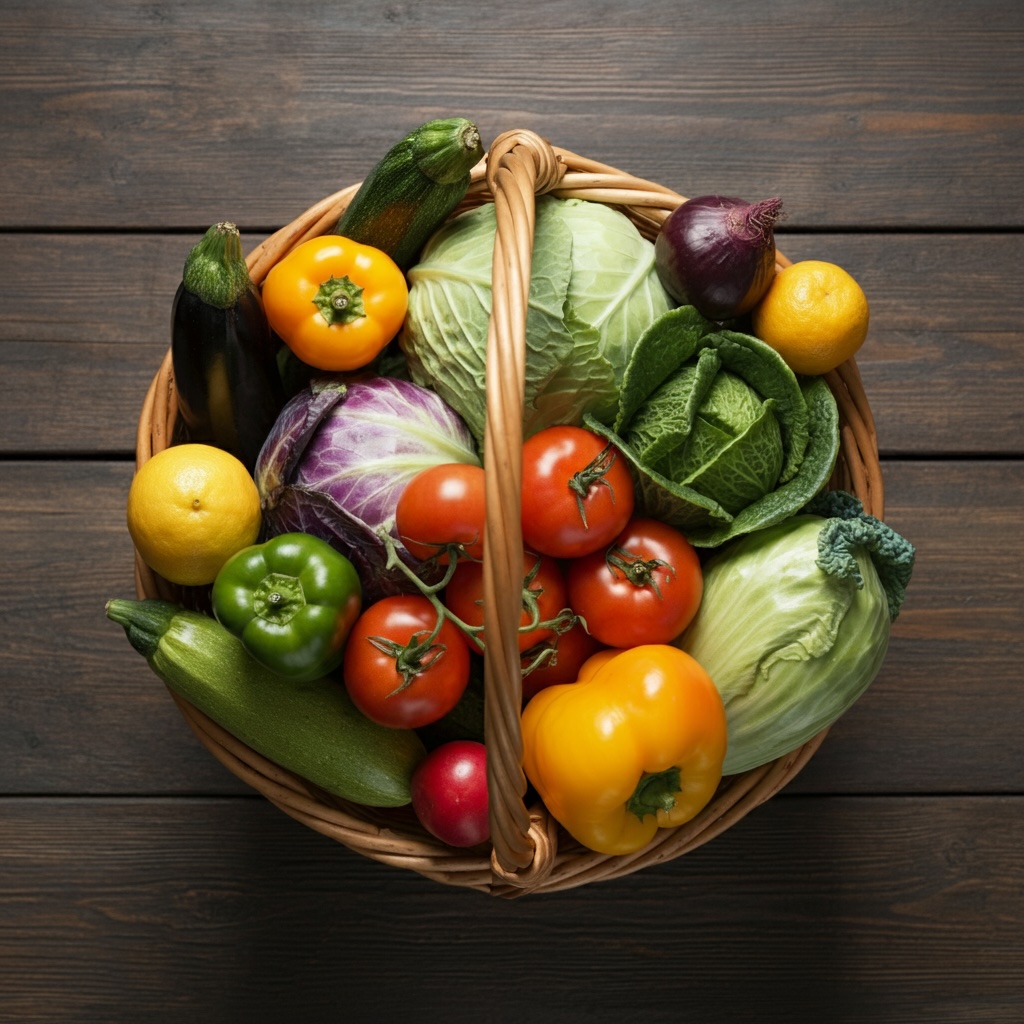
Object detection
od
Supported inputs
- textIgnored
A text part beside the media is accepted and ignored. A request with no media part is a
400. - image_urlYes
One per request. A second
image_urlpart is a400. - video_urlNo
Not accepted.
- document_urlNo
Not accepted.
- Default method
caption. The caption andocrmethods emit a Markdown string; the region methods emit a region container. - Alias:
microsoft/Florence-2-base-ft. Weights:microsoft/Florence-2-base-ft.
Methods
Methods this model serves. Payload shapes are in the docs.
| Method | Returns |
|---|---|
| caption (default) | Short image caption |
| detailed_caption | Longer caption |
| more_detailed_caption | Longest caption |
| ocr | All text on the image |
| od | Region items with bbox_xywh and label |
| dense_region_caption | Region items with bbox_xywh and label |
| region_proposal | Region items with bbox_xywh, no label |
| ocr_with_region | Region items with bbox_xywh and text |
Each method maps to one Florence-2 task token. The task token itself (<CAPTION>, <OD>, ...) is an implementation detail and is not part of the reply: a caption is the string, and a region method is the container.
Boxes are normalized 0-1 against the image at precision decimals (default 4), and a region method with no hits returns "items": [].
Estimate cost
$0.00
Quick start
Call this model on the OpenAI-compatible gateway. The model id is already filled in.
Response
The caption string alone, with no wrapper:
A cat sitting on a windowsill.